Performance Tuning
Processing cost is driven by how many frames are analysed, at what resolution, and by how many faces per minute reach extraction, liveness and matching. Tune in this order: right-size the input (resolution, intervals, preview), move the heavy services to the GPU, then add replicas. Each step below names the setting and where it lives.
Scale the busy services
Every service runs on a single core, so throughput comes from replicas. The extractor is usually the first service to saturate; matchers follow on large watchlists. See Scaling for what to replicate and how.
Use the GPU where it helps
Detection, extraction and liveness gain the most from a GPU, and camera containers can decode video on it as well. See GPU acceleration.
Use only the resolution you need
Full HD (1920 x 1080) is the recommended stream resolution. Higher resolutions bring diminishing returns for face detection while the decoding and detection cost grows steeply. Use the camera's Full HD stream or sub-stream rather than 4K, and get face size from lens choice and placement instead, as described in Camera selection and placement.
Detection and extraction intervals
Detection and extraction are the expensive repetitive operations on a stream. A camera runs detection at the detection interval; between detections it only tracks the faces it already knows. Extraction runs at the extraction interval on tracked faces. Both default to 500 ms, which means two detections and two extractions per second per camera.
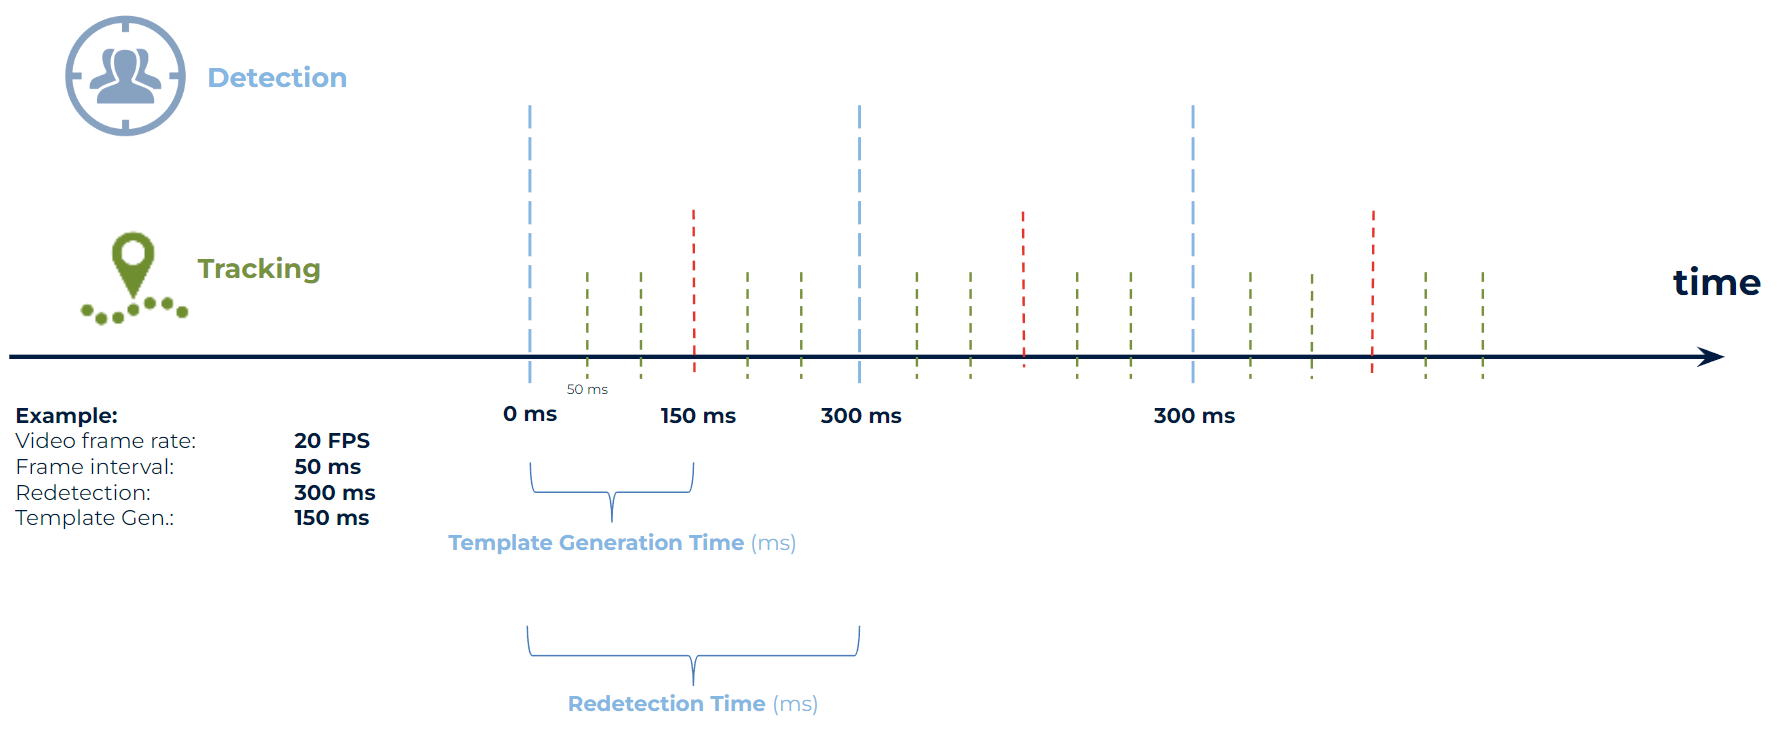
- Keep both intervals equal, or make the detection interval a whole multiple of the extraction interval.
- Where every person must be caught (gates, entrances, corridors) start at 250 ms for both. If people pass even faster, halve the values step by step and watch the CPU or GPU load.
- Where traffic is slow, longer intervals cut the load with no loss.
The intervals are per camera and are set in Station or through the REST API /api/v1/Cameras endpoint; see the camera settings reference.
Camera preview
The live preview that Station shows is encoded by the camera container and costs CPU on the server. On a small machine turn it off for cameras nobody watches, and pick the lowest quality that is still useful. The presets are Low (426 px height), Medium (640 px) and High (1280 px); a custom height and bit rate can be set through the REST API only. See the camera settings reference.
Liveness and algorithm choice
Server-side liveness runs only on matched faces by default (SpoofDetection__SkipUnidentified=true in .env, section 2.17). Setting it to false evaluates every face and multiplies the liveness load; enable liveness only on cameras that need it. The detection algorithm (fast, balanced_mask, accurate_mask) and the extraction algorithm (fast, balanced, accurate, accurate_server) trade accuracy for speed; balanced is the default for both. Changing the extraction algorithm on a system that already holds templates requires a template migration, so decide it at installation time. Settings are listed in Detection and matching settings.