GPU Acceleration
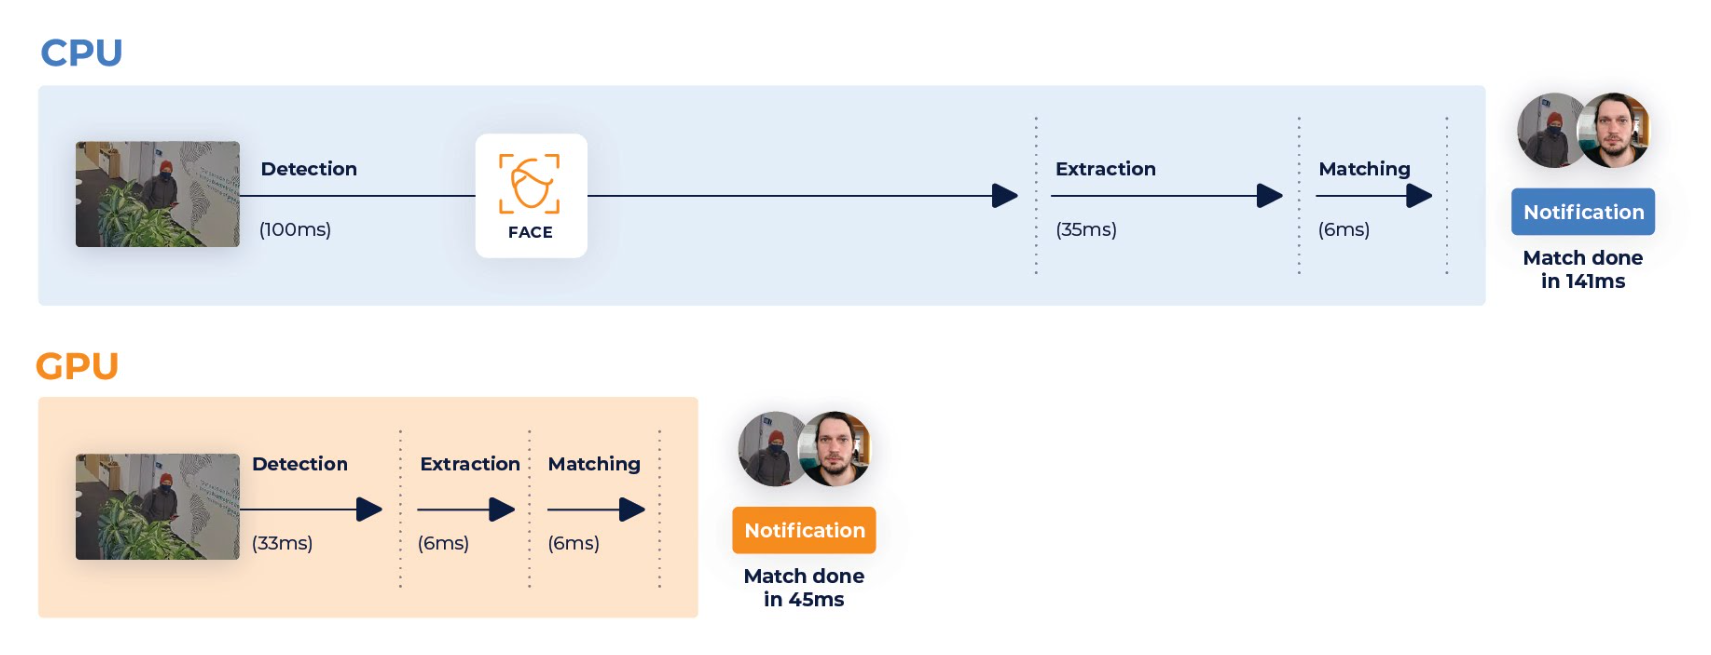
Detection, extraction and liveness are neural-network workloads that run several times faster on a GPU than on a CPU. Face Matcher supports NVIDIA GPUs only. GPU use is configured per service: you can put the extractor on the GPU and leave the cameras on the CPU, or decode video on the GPU as well. The timings below are illustrative.
Host prerequisites
- An NVIDIA GPU with CUDA support. The more video memory the better: every GPU-enabled container loads its own models.
- A recent NVIDIA driver. The previous platform generation required CUDA 11.8 and driver version 520.61 or later.
- The NVIDIA Container Toolkit configured for Docker, so that
runtime: nvidiais available to Compose.
Check the toolkit before touching Face Matcher: docker run --rm --runtime nvidia --gpus all ubuntu nvidia-smi must print the GPU.
Settings
Section 2.9 of .env holds the GPU settings. They are shared by every GPU-capable service: base, cam-*, detector, extractor, liveness, pedestrian-detector, pedestrian-extractor and object-detector.
| Setting | Values | Meaning |
|---|---|---|
Gpu__GpuEnabled | true, false | Run neural networks on the GPU. A service with true and no GPU available does not start. |
Gpu__GpuDeviceIndex | 0, 1, ... | Which GPU to use on a multi-GPU host. Relevant with the Default runtime. |
Gpu__GpuNeuralRuntime | Default, Cuda, Tensor | Acceleration runtime; only applies when GpuEnabled is true. Tensor (TensorRT) is the fastest and needs a GPU that supports it. |
Setting Gpu__GpuEnabled=true in .env switches every GPU-capable service at once, and each of them then needs the NVIDIA runtime. To enable the GPU selectively, keep .env at false and set the variables on individual services in docker-compose.override.yml.
Enable the GPU for a service
services:
  extractor:
    runtime: nvidia
    environment:
      Gpu__GpuEnabled: "true"
      Gpu__GpuNeuralRuntime: Tensor
    volumes:
      - /var/tmp/innovatrics/tensor-rt:/var/tmp/innovatrics/tensor-rt
TensorRT builds an optimised engine the first time a model is loaded. This takes from seconds to a few minutes, and the service does not answer requests until it is done. The /var/tmp/innovatrics/tensor-rt volume keeps that cache on the host, so recreated containers start fast. Apply with docker compose up -d and watch docker compose logs -f extractor for the GPU initialisation. Replicas of a GPU service (see Scaling) share the GPU selected by Gpu__GpuDeviceIndex.
Hardware video decoding on cameras
Camera containers can also decode RTSP on the GPU. Set runtime: nvidia on each cam-N service and give it a GStreamer pipeline through GstPipelineTemplate (section 3.6 of .env), where {0} is replaced by the camera's RTSP URL. The default GstPipelineTemplate={0} uses the built-in software pipeline. The release .env carries both templates as comments:
# x86 host with an NVIDIA GPU
GstPipelineTemplate=uridecodebin uri={0} source::latency=0 ! queue max-size-buffers=1 leaky=downstream ! nvvideoconvert ! video/x-raw, format=(string)BGRx ! videoconvert ! video/x-raw, format=(string)BGR ! appsink

# NVIDIA Jetson
GstPipelineTemplate=uridecodebin uri={0} source::latency=0 ! queue max-size-buffers=1 leaky=downstream ! nvvidconv ! video/x-raw, format=(string)BGRx ! videoconvert ! video/x-raw, format=(string)BGR ! appsink
GstPipelineTemplate in .env applies to all cameras. To mix GPU-decoded and CPU-decoded cameras, set the variable per service in the override file instead. Face detection inside the camera container follows Gpu__GpuEnabled in the same way, so a camera with the NVIDIA runtime can decode and detect on the GPU. Camera stream settings are described in Server-side RTSP cameras.